
Analysis · 21 September 2026 · WW3.press
The AI race is a contest
for the infrastructure
of power.
The struggle over advanced AI reaches beyond a contest between chatbots. It is a contest over the machinery, access and institutions through which intelligence becomes power.
“World War III” is the frame of this essay, not a claim that a world war between technology companies has begun. Commercial rivalry, espionage and armed conflict are different things.
01. A refinery for intelligence
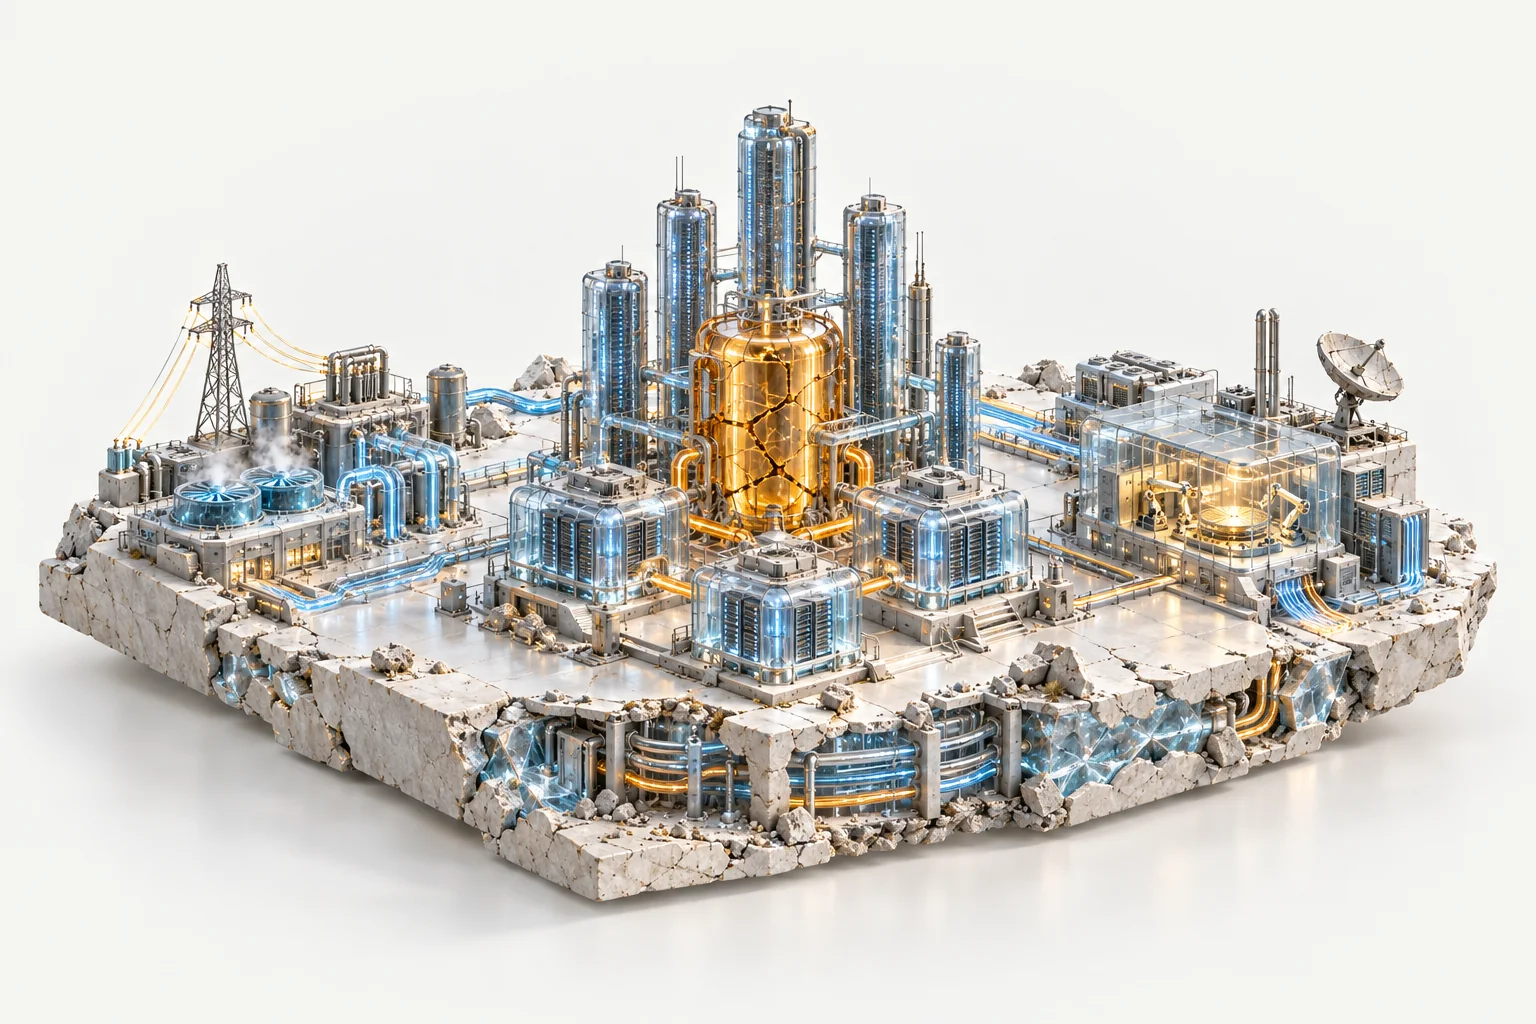
The object above is imaginary. The dependency it represents is not. A model reaches a person through a chain of computing systems, infrastructure and organizational decisions. Calling the result “the cloud” makes the physical part easy to forget.
In its April 2025 report, the IEA projected that global data-centre electricity use would more than double to around 945 TWh in 2030. That is a forecast for the whole data-centre sector, with AI an important growth driver—not a measurement of AI's current demand. The report also identifies grid-connection delays as a constraint. [7]
The refinery is a useful visual analogy because it asks us to look at inputs, conversion and distribution. It has a limit: intelligence is not a barrel of oil. Models can be copied, improved and deployed in very different ways. The illustration is a map of questions, not an engineering model.
02. The rivals share pipes
The easiest story puts each company behind its own flag. The evidence is more interesting. Anthropic says Claude uses AWS Trainium, Google TPUs and NVIDIA GPUs. In April 2026 it announced additional Google/Broadcom capacity expected to start coming online in 2027. [2] Google develops Gemini as well as its own accelerators. [3][4]
OpenAI's original Stargate announcement, in January 2025, likewise described a network of funders and technology partners. Its proposed $500 billion investment over four years was a stated intention—not a receipt for completed infrastructure. [1]
That is the tension at the heart of this project. Competition does not eliminate dependence. It can intensify it. A lab can seek independence from one supplier while tying itself more closely to another. Our interpretation is that control of the connections may matter as much as a temporary lead in model performance.
03. Beyond two teams
“Chinese models” is a category, not a single competitor. DeepSeek and Alibaba's Qwen have different organizations and model families behind them. The DeepSeek-R1 and Qwen3 repositories document examples of publicly released weights and ways for other people to build on those releases. [5][6]
Those examples complicate a closed contest between a few hosted products. A model can spread through developers, local deployments and downstream services. Open weights do not guarantee that training data, every training step or every later release is equally open. Each release needs its own examination.
This is also why the five names in our explorer are a starting point. They are not a claim that the rest of the industry, academic research or the people using these systems have ceased to matter.
04. Where conflict becomes real
The metaphor becomes serious when AI systems are used in security operations. In November 2025, Anthropic reported an espionage campaign misusing Claude Code and assessed the operator as Chinese state-sponsored. That attribution and the account of the operation come from Anthropic; this essay has not independently verified its incident evidence. The company also acknowledged model errors and described defensive uses of the same capabilities. [8]
That report is not evidence that Chinese model developers directed the operation, or that AI labs are attacking their commercial rivals. Connecting those dots without evidence would turn an explainer into a conspiracy story.
Cyber operations, proxy conflicts and conventional warfare are potential contexts in which AI may matter. They do not belong in one undifferentiated bucket. A commercial partnership, a government decision and a military act each require their own sources, actors and standards of proof.
05. A finish line worth questioning
“The race to AGI” sounds as if somebody installed a finish line. The research picture is less tidy. The Levels of AGI framework separates performance and generality, and considers autonomy and deployment risk as additional dimensions. It is a proposal for making comparisons clearer, not a universal referee. [9]
Our position is that a useful public discussion should ask what a system can do, under which conditions, at what cost, with which permissions and with what degree of reliability. A dramatic label cannot answer those questions.
There is a bigger struggle here than a product launch. It concerns whose tools become indispensable, who can deny access, and who gets to define an acceptable risk. Calling that a world war is provocative. Making its dependencies visible is the useful part.
06. What to watch
Watch for operating capacity rather than announced capacity. Watch the terms under which people can use and modify a model. Watch the difference between a capability demonstration and reliable deployment. And when a security claim appears, ask who observed it, what evidence is public and what remains uncertain.
The answer is not a countdown to an inevitable catastrophe. It is a habit of following the connections—and checking whether the story survives contact with its sources.
Independent analysis.
Evidence you can follow.